AI Evaluation Metrics: What to Measure in Production
Choose AI evaluation metrics that connect model behavior to task outcomes, reliability, cost, latency, safety, and user impact.
In this guide38 sections
At a glance

This diagram is a topic-specific decision aid: connect the article’s context to evidence before taking the next action.
This guide is for engineers evaluating LLM and AI agent changes. It helps you choose metrics that support a release decision. It does not claim that one score can represent every user, risk, or workflow.
The evaluation scorecard
Use Outcome → Quality → Reliability → Economics → Safety. Start with the user task, then add dimensions that explain whether a change is acceptable.
Measure the task first
Define what successful completion means and how failure affects the user. For a RAG answer, that may include groundedness and citation correctness. For a tool-using agent, it may include correct tool selection, argument validity, and side-effect accuracy. AI agent evaluation covers how to build that decision path.
| Dimension | Example question |
|---|---|
| Outcome | Did the user task finish correctly? |
| Quality | Was the answer relevant and supported? |
| Reliability | Did tools and dependencies behave? |
| Economics | What did the run cost and how long did it take? |
| Safety | Did the workflow stay inside policy? |
Build the measurement system
Pair aggregate scores with traces
An average can hide a severe regression in a small cohort. Store evaluator version, candidate version, task distribution, sampled examples, and failure class. Inspect traces for the mechanism behind the score. AI agent testing shows how unit tests, regression cases, and production evaluations fit together.
Set decision thresholds before looking
Write the baseline, acceptable regression, required improvement, and stop condition before comparing candidates. If the sample is small or the evaluator is noisy, state that uncertainty. A precise number without a stable sampling rule is not strong evidence.
Calibrate metrics before using them as gates
Run the evaluator on examples whose expected interpretation is already understood. Compare automated labels with a small human-reviewed sample and record disagreement reasons. Calibration does not prove that an evaluator is correct everywhere; it reveals where the metric is dependable, where it is noisy, and where a human must remain in the loop.
Watch distribution changes
A score can improve because the traffic became easier. Compare cohorts, task mix, language, release, and input length. Preserve the sampling rule and report excluded cases. If the distribution changes materially, describe the result as a new baseline rather than presenting it as a clean before-and-after improvement.
Connect metrics to actions
For each metric, name the owner and response. A groundedness regression may trigger retrieval investigation; a latency regression may trigger trace inspection; a safety disagreement may pause a rollout. If a metric never changes a decision, remove it or move it to a lower-cost review. More metrics do not create more control.
Review metric health
Revisit evaluator drift, missing labels, stale references, and reviewer fatigue. The measurement system is part of the product and can fail independently of the agent. Keep a small set of known cases that should remain stable and inspect them whenever the evaluator, prompt, model, or data changes.
Define the unit of evaluation
The unit should match the decision you are making. A single model response may be enough for a formatting check, but it is too small for a workflow where retrieval, tools, approvals, and retries determine the result. Define whether one example is a message, task, session, case, or complete run. Preserve the sampling rule so a score remains comparable after the system changes.
Separate dimensions that answer different questions
Relevance, factual support, task completion, tool correctness, latency, cost, safety, and user satisfaction are related but not interchangeable. Report them separately before creating a summary score. If a weighted score is useful for a release gate, publish the weights and show the component movement. A score that hides a safety regression is worse than several imperfect measures that expose the trade-off.
| Metric family | Evidence | Decision |
|---|---|---|
| Task outcome | Expected and actual result | Does the workflow work? |
| Grounding | Source and claim comparison | Is the answer supported? |
| Tool use | Selected tool and arguments | Is the action correct? |
| Reliability | Failure and retry classes | Can it complete consistently? |
| Economics | Usage, duration, retries | Can it operate affordably? |
Build a representative evaluation set
Start with common cases, then deliberately add the tails: long inputs, ambiguous requests, empty retrieval, conflicting sources, permission boundaries, rare languages, malformed tool responses, and high-consequence actions. Keep production examples redacted and label their cohort and failure mechanism. A set made only from successful demos will reward systems that optimize for the wrong distribution.
Keep evaluator changes visible
An evaluator is part of the measurement system. Version its rubric, model, prompt, reference data, and post-processing. Re-run a stable calibration set when it changes. If scores move after an evaluator update, do not attribute the movement to the product candidate until both versions have been compared on the same examples.
Use human review where it adds information
Human review is most valuable for ambiguous, novel, high-consequence, or evaluator-disagreement cases. Give reviewers the task, expected boundary, output, relevant trace evidence, and rubric version. Measure agreement and review time, but do not turn disagreement into a forced consensus without recording why reviewers differed.
Turn failures into regression coverage
When a production run fails, preserve a safe fixture containing the input shape, relevant context, expected behavior, actual behavior, and failure class. Remove secrets and personal data. Add the fixture to the smallest test layer that would catch the mechanism: schema validation, tool policy, retrieval check, evaluator, or end-to-end scenario. AI agent regression testing shows how this creates a learning loop instead of a dashboard of recurring surprises.
Set promotion rules before comparison
Write the baseline, minimum improvement, maximum acceptable regression, confidence caveat, and rollback owner before looking at candidate results. For small samples, report uncertainty and inspect individual disagreements. For large samples, watch for a statistically visible but practically irrelevant change. Release gates should protect the user outcome and the dimensions that matter to the business, not merely reward a better average.
Start with a decision inventory
Before selecting metrics, list the decisions the team expects evaluation to support. A product owner may need to decide whether a workflow is useful enough to launch. An engineer may need to decide whether a prompt change fixed a regression. An operator may need to decide whether a rising failure rate requires a rollback. A safety reviewer may need to decide whether a new tool should remain behind approval. Each decision needs different evidence, even when the same run contributes to all of them.
Distinguish quality from completion
Completion means that the workflow reached a terminal state. Quality means that the terminal state was correct and useful. A support agent can close a case with an incorrect answer; a research agent can produce a fluent summary that omits the decisive source; a booking workflow can call the right tool with the wrong date. Track terminal status separately from task correctness so a healthy queue does not hide poor outcomes.
Distinguish correctness from confidence
A model or evaluator confidence score describes an estimate, not a guarantee. Compare confidence with reviewed correctness by cohort. Look for confident errors, uncertain correct answers, and cases where confidence changes after retrieval or tool use. Use the disagreement to decide whether to ask a clarification, require approval, or improve the evidence path. Never turn a confidence threshold into an authorization policy without testing its failure cost.
Build a metric taxonomy
Organize metrics by the layer they describe. Task metrics describe the user-visible result. Evidence metrics describe whether the system had the information needed to act. Execution metrics describe model, retrieval, and tool behavior. Operational metrics describe time, cost, retries, and availability. Governance metrics describe policy, approval, redaction, and audit behavior. The taxonomy prevents a team from comparing unrelated numbers or assigning one owner to a signal that crosses several responsibilities.
| Layer | Examples | Typical owner |
|---|---|---|
| Task | Correct resolution, grounded answer, successful action | Workflow owner |
| Evidence | Retrieval recall, citation support, freshness | Data or search owner |
| Execution | Tool selection, schema validity, retry class | Application owner |
| Operations | p95 latency, spend, queue delay, failure rate | Platform owner |
| Governance | Approval compliance, policy blocks, redaction | Security or risk owner |
Keep the denominator visible
Every percentage needs a population. State whether the denominator is all runs, completed runs, eligible examples, reviewed samples, or a particular cohort. Exclude cancelled or unsupported cases only with a documented reason. A success rate can rise when difficult cases disappear from the denominator. Preserve counts next to rates so a reviewer can judge whether a change is meaningful.
Design an evaluation dataset
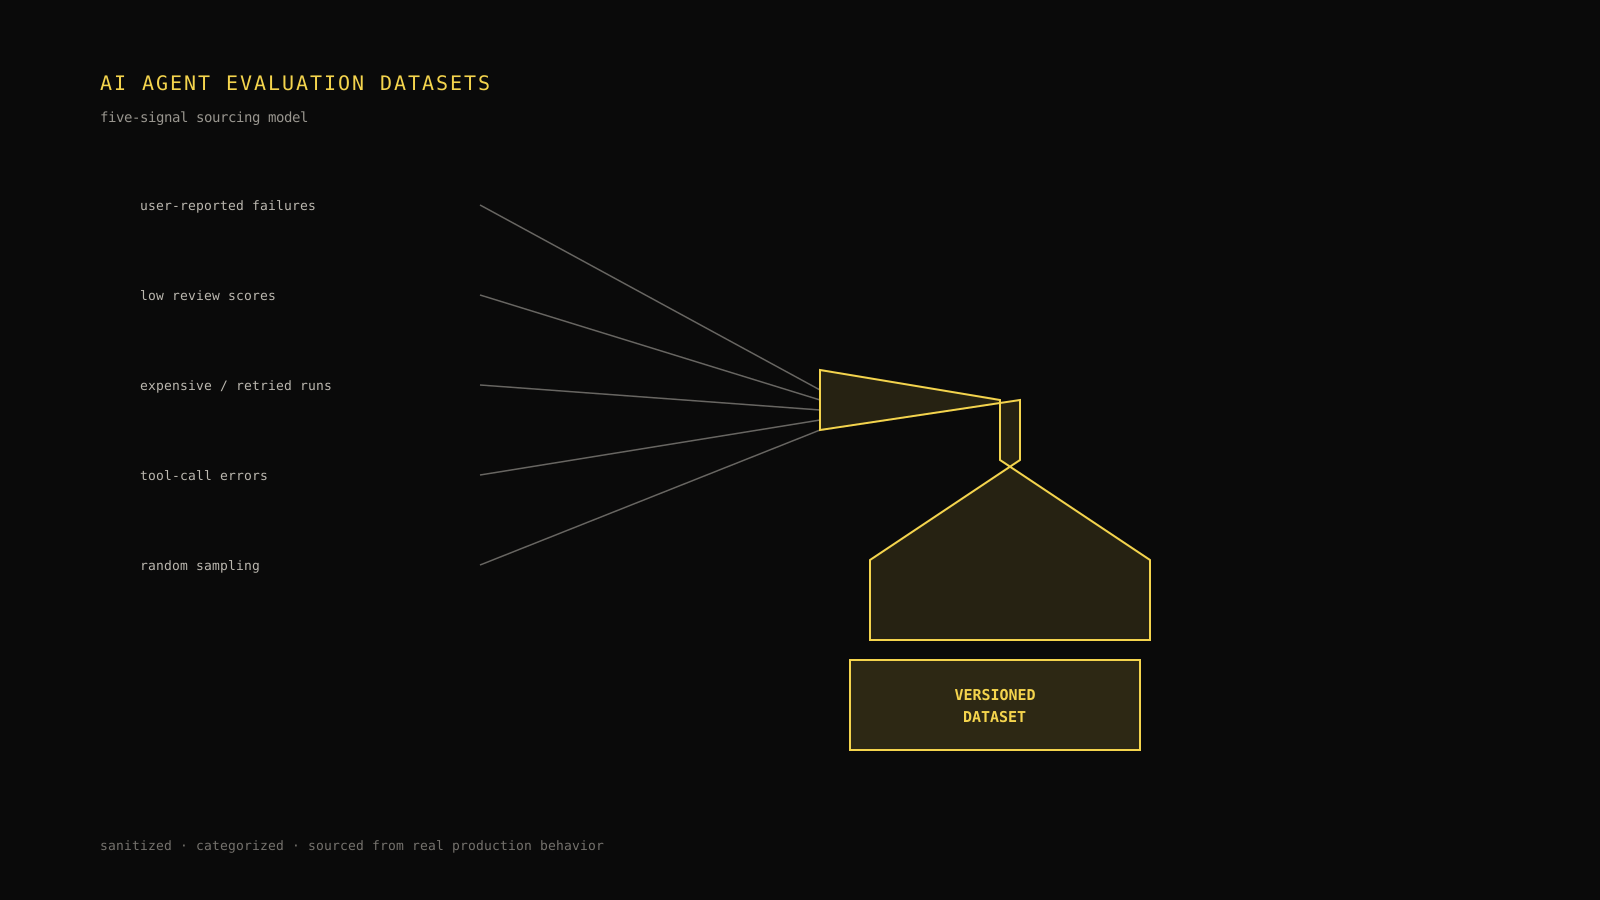
Combine curated regression cases, redacted production samples, incident examples, and expert-authored boundary cases. Label source, cohort, date, expected outcome, and failure mechanism. Include long inputs, ambiguous requests, empty retrieval, conflicting sources, malformed tool responses, missing permissions, repeated events, timeouts, and high-consequence actions. The right tail may be small but still important because its failure cost is large.
Protect evaluation data
Remove secrets and unnecessary personal data from fixtures. Keep a mapping to controlled source records only when an authorized reviewer needs it. Test that examples do not leak into prompts, public logs, or developer screenshots. An evaluation dataset can become a sensitive production copy if its retention and access rules are not explicit.
Calibrate automated evaluators
An evaluator should have a rubric, input contract, output schema, version, and known limitations. Run it against a calibration set with human judgments. Examine disagreements by mechanism: ambiguous reference, evaluator misunderstanding, missing context, label inconsistency, or genuinely difficult case. Improve the rubric or route the case to review instead of treating disagreement as noise.
Watch evaluator drift
Evaluator drift can come from a changed judge model, prompt, reference data, parser, threshold, or sampling rule. Keep those versions with every score. Re-run a stable calibration set after changes and compare the distribution. If a metric moves while the product candidate is unchanged, investigate the evaluator first.
Use human review efficiently
Route novel, high-impact, evaluator-disagreement, and threshold-adjacent cases to reviewers. Show the task, expected boundary, output, relevant trace evidence, and rubric. Ask for a disposition and reason, not only a binary score. Give reviewers a shared calibration set and sample previously reviewed cases again to detect drift. Improve case selection before lowering the quality standard when review burden grows.
Connect metrics to traces
An aggregate score tells you that something moved; a trace helps explain why. Attach evaluator version, candidate version, task cohort, sample rule, and failure class to the run. Link the score to retrieval evidence, prompt version, tool calls, retries, approvals, latency, and cost. Preserve baseline and candidate outputs together so the release decision remains reproducible.
Design layered release gates
Start with deterministic checks such as schema validity, tool permissions, and known security fixtures. Add offline quality and regression evaluation. Then use shadow or canary traffic with monitoring and a rollback condition. A fluent answer cannot excuse a forbidden action, and a lower cost cannot excuse a task failure. Write the gate before viewing results so the standard does not move to fit an attractive candidate.
Turn incidents into evaluation coverage
After an incident, preserve the mechanism rather than only the transcript. Describe input shape, expected behavior, actual behavior, affected version, evidence available, and missing control. Create a redacted fixture and add it to the smallest appropriate layer. Re-run it against candidate and baseline, then record whether the change fixes the mechanism without harming neighboring workflows. Retire stale cases with a reason instead of silently deleting history.
Establish an operating cadence
Review candidates before promotion, representative samples during normal operation, and metric health after evaluator or data changes. Assign an owner to every gate and a response to every threshold. Keep a short decision record with baseline, candidate, evidence, trade-offs, unresolved risk, and next review date. This turns evaluation from a launch activity into a feedback loop for the entire AI system.
Read disagreement as evidence
The most useful evaluation examples are often the ones where systems or reviewers disagree. Preserve the complete comparison: same task, relevant context, candidate and baseline outputs, tool calls, citations, evaluator versions, and reviewer disposition. Then classify the disagreement as a genuine quality change, interpretation change, missing reference answer, tool or retrieval difference, evaluator noise, or a task that should not have been scored by the current rubric.
Separate the first divergence
For an agent workflow, inspect the sequence in order. Did the system interpret the request differently? Did it retrieve different evidence? Did it choose a different tool? Did argument validation reject or alter the proposal? Did a dependency fail? Did the final answer misrepresent a correct intermediate result? Finding the first divergence makes the next experiment smaller. Without it, teams often rewrite prompts to compensate for a data, schema, or policy problem.
Keep reviewer reasons structured
Offer a small set of failure mechanisms with an optional explanation: unsupported claim, incomplete task, wrong tool, invalid argument, unsafe action, stale evidence, poor communication, or evaluator error. Let reviewers identify multiple causes when necessary. These labels should describe what happened, not assign blame to a model or person. Over time, the distribution tells the team which layer deserves the next investment.
Understand cohort drift
A production score can change even when the implementation does not. User questions may become longer, a new customer segment may arrive, a source corpus may change, or traffic may move from a batch workflow to an interactive one. Track task class, input length, language, tenant or plan where appropriate, model, prompt, tool set, and date. Compare cohorts before making a claim about regression or improvement.
Use stable and adaptive sets
A stable set protects comparability. Keep it unchanged long enough to detect meaningful movement and version it when policy or product behavior makes a case invalid. An adaptive set reflects current traffic and discovers new failures. The stable set answers “did known behavior change?” while the adaptive set answers “what is the system encountering now?”
Treat missing examples as a signal
If a task class cannot be evaluated because the expected outcome is unclear, mark it as unscored and record why. Decide whether to clarify the contract, collect human labels, or route the workflow to review. An honest unknown is more useful than a false pass.
Measure reliability around the task
Include timeout, retry, tool error, cancellation, approval, and fallback outcomes. A candidate that improves quality by making three times as many calls may be unacceptable. A candidate that reduces latency by skipping validation may create hidden risk. Connect every operational metric to the task and its user impact.
| Movement | Follow-up question |
|---|---|
| Quality up, cost up | Is the value worth the spend by cohort? |
| Latency down, quality down | Which evidence or validation disappeared? |
| Success up, review up | Are cases safer or merely deferred? |
| Failure down, unknown outcomes up | Is the system hiding provider ambiguity? |
| Score stable, complaints up | Does the rubric represent the task? |
Test evaluator failure modes
Evaluators can fail through truncated context, parser errors, malformed outputs, rubric ambiguity, judge-model changes, reference leakage, and score saturation. Add health checks for missing scores, impossible values, unexpected label distributions, and a sudden rise in passes without a corresponding task improvement. Monitor the evaluator as an operational dependency so its failure does not look like a product improvement.
Compare evaluators on a fixed panel
Maintain a small panel of cases with human-reviewed dispositions. Run every evaluator revision against it. Look at both agreement and individual cases that changed. If the evaluator becomes more permissive, a higher product score may not mean the product improved. Store panel results with the evaluator release record.
Make safety and policy non-negotiable
Some evaluation dimensions are not ordinary trade-offs. A system may tolerate a small latency increase to preserve a required approval, but it should not accept an unauthorized action because answer quality improved. Define hard gates for non-negotiable boundaries: forbidden tools, cross-tenant access, secret exposure, disallowed content, and missing approvals. Test them deterministically where possible and review borderline cases manually.
Evaluate refusal quality
A refusal is not automatically a success. It may be a correct boundary, an unnecessary block, or a vague response that leaves the user without a safe next step. Score whether the refusal identifies the limitation accurately, avoids exposing policy details, offers an allowed path when one exists, and records the reason for operators. Include benign requests so the system does not optimize for refusing everything.
Design canary evaluation
Offline evaluation cannot capture every integration effect. During a canary, compare candidate and baseline by task class, not only by global average. Route the candidate to a narrow cohort, retain a clear baseline, and watch outcome quality, failure classes, cost, latency, policy events, and user repair behavior. Decide how long the canary must run or how many representative cases it needs before promotion. A canary without a stop condition is only an observation period.
Monitor after promotion
The release decision does not end evaluation. Sample production runs after promotion and compare them with the pre-release baseline. Watch for delayed failures, stale retrieval, changed user behavior, provider drift, and evaluator changes. Link alerts to representative traces and an owner. If a metric moves, inspect the distribution and execution path before changing a threshold or rolling back.
Write and preserve the decision record
A release record should state candidate and baseline, task distribution, dataset and evaluator versions, metric movement, reviewed disagreements, safety results, known limitations, rollout scope, owner, and rollback condition. Include the decision itself: promote, hold, narrow, repair, or reject. Preserve rejected candidates with their evidence and reason; negative results prevent the team from repeating the same experiment.
Choose the next action from the metric
If task quality is low and retrieval recall is low, investigate ingestion or search before rewriting the answer prompt. If retrieval is strong but citations are wrong, inspect context assembly and output validation. If tool selection is correct but arguments are invalid, strengthen the schema or policy boundary. If scores are stable but users repair outputs, revisit the task definition and evaluator. The purpose of metrics is to narrow the next decision, not to create another dashboard surface.
Keep the operating loop small
After each review, choose one owner, one hypothesis, one bounded change, and one follow-up measure. Avoid opening many simultaneous experiments that cannot be compared. Preserve the baseline and use a reversible rollout. This keeps evaluation connected to engineering work and prevents the team from accumulating scores without a learning loop.
Avoid single-score release culture
Teams often want one number because one number is easy to report. The danger is that the score becomes the product objective even when it is only a proxy. Keep the summary score if it helps a decision, but show its components, sample size, uncertainty, and guardrails beside it. A candidate that wins the summary while failing a mandatory safety check has not won the release. A candidate that loses a noisy judge score while improving the user outcome deserves investigation rather than automatic rejection.
Review examples that changed the decision
For each promotion, hold out time to read examples where the baseline passed and the candidate failed, where the candidate passed and the baseline failed, and where both systems received surprising scores. Ask what mechanism changed and whether the rubric captures the intended task. This review is not an alternative to measurement; it is how a team checks that the measurement remains connected to reality.
Connect evaluation to ownership
The person who owns a metric should know what evidence to open and what action is available. A retrieval owner can inspect source versions and ranking. A workflow owner can inspect tool selection and task outcome. A platform owner can inspect latency, provider failures, and retries. A safety owner can inspect policy decisions and approvals. Cross-functional evaluation works when the trace and decision record make those handoffs explicit.
Record unresolved uncertainty
Some results will be inconclusive because the sample is small, labels disagree, or the task boundary is changing. Record the uncertainty and choose a bounded next measurement. Do not turn an inconclusive result into a confident promotion merely because the schedule is tight. A clear hold with an owner and evidence plan is a valid engineering decision.
Evaluate the evaluator’s cost
Judges, reviewers, reference retrieval, and repeated candidate runs consume time and money. Include those costs in the evaluation plan. Use deterministic checks for cheap, high-volume conditions and reserve model or human review for cases where it adds information. Cache only when the cache key includes the versions and inputs that affect the result. A low-cost evaluator that cannot distinguish important failures is not efficient; it is under-measuring the system.
Close the loop after recovery
When a release is rolled back or a workflow is repaired, re-run the affected cases against the restored baseline and the failed candidate. Confirm that the user-visible outcome recovered and identify whether the gate should have caught the issue earlier. Add the mechanism to regression coverage, update the evaluator or rubric if needed, and record the final disposition. Recovery is incomplete when the same failure can return without producing stronger evidence.
The evaluation review packet
Use the packet during release review and post-release follow-up.
Keep the packet small enough to use and complete enough to defend the decision. Include links to source dashboards, evaluation artifacts, and representative run IDs, but do not turn it into a second uncontrolled data store. State what was measured, what was not measured, how the sample was selected, and which claims are still uncertain. This makes later review faster when the model, evaluator, traffic mix, or product promise changes. Keep an explicit owner for refreshing the packet and the evaluation set. Review it after incidents, evaluator changes, and material shifts in the workflow.
Keep one compact packet for every material candidate: task definition, cohort, baseline, candidate, evaluator and dataset versions, component metrics, safety results, disagreements, cost and latency movement, unresolved risks, rollout scope, owner, and rollback rule. Link to representative traces rather than copying sensitive output into a separate document. The packet should let a new reviewer reconstruct the decision without relying on a meeting or an informal explanation.
Ask whether the metric changed behavior
Schedule a review after incidents, evaluator changes, and material workflow shifts. Archive prior packets so historical release decisions remain interpretable when the system evolves.
After a release, check whether the team used the metric as intended. Did it lead to a prompt change, a retrieval repair, a tool policy, a canary pause, or a decision to accept the risk? If no action followed repeated movement, the metric may be poorly owned or too detached from the workflow. Refine the signal, change its cadence, or remove it so the evaluation system remains useful rather than decorative.
The final standard is practical: evaluation should make a user-visible decision safer, clearer, or more reversible. If a score cannot help someone decide what to inspect or change next, it does not yet earn a place in the production scorecard.
Turn the scorecard into a release room
Metrics become useful when a real team can use them under time pressure. Imagine two candidate models for a support workflow. Candidate B improves answer relevance by four points, but tool-call failures double for refund requests. The right question is not “which model scored higher?” It is “which change produces the better customer outcome inside the allowed risk and operating budget?”
| Release question | Evidence to put on the table | Decision owner |
|---|---|---|
| Did the task get completed? | Expected outcome versus terminal state | Workflow owner |
| Was the result correct? | Rubric score plus reviewed examples | Product or domain owner |
| Did the system stay dependable? | Timeouts, retries, tool failures, unknown outcomes | Platform owner |
| Did the improvement pay for itself? | Cost and latency by cohort | Engineering owner |
| Did it stay inside policy? | Blocks, approvals, unsafe proposals, refusal quality | Risk owner |
Field note: Never let a single averaged score speak for a workflow with side effects. Put the score beside the traces that explain its movement.
A metric has a job
Give every metric one sentence: “This changes our decision when…” If the sentence cannot be finished, the metric is decoration. A groundedness score might decide whether retrieval needs investigation. A p95 latency measure might decide whether streaming or caching needs work. A refusal-quality measure might decide whether a workflow stays behind human approval.
This small test also exposes duplicate metrics. If task completion, answer quality, and user acceptance all move together on the same sample, keep the one that best represents the decision and use the others as diagnostics. A smaller board is easier to explain, cheaper to run, and harder to game.
Read one evaluation like a story
A production evaluation should be readable from left to right. Start with the request, then follow the evidence, the model decision, the tool path, and the user-visible result. The first divergence is usually more valuable than the final score.

Read the run from left to right. Stop at the first meaningful change before diagnosing the final symptom.
| Moment | What to inspect | What it can explain |
|---|---|---|
| Request | Task class, language, input length, expected outcome | Cohort drift or a bad contract |
| Evidence | Retrieved sources, freshness, permissions | Unsupported or stale answers |
| Decision | Prompt/model version and structured output | Changed reasoning or schema behavior |
| Execution | Tool arguments, retries, approvals, provider status | Side-effect and reliability failures |
| Outcome | Final state, correction, review, complaint | Whether the task actually worked |
For example, a candidate may have the same answer-quality score as baseline while producing more clarification requests. That can be good if ambiguous cases are being handled safely. It can be bad if the candidate lost access to a required field. The trace tells you which story is true.
The denominator is part of the plot
“92% success” is unfinished information. Name the population, the count, and the exclusions. Say “92 of 100 eligible refund cases” rather than “92%.” If cancelled runs, unsupported languages, or missing labels were excluded, show them beside the result. A rising percentage can simply mean that difficult work stopped entering the sample.
Decision rule: A metric without its denominator, cohort, evaluator version, and owner is a signal, not a release gate.
Build a small but difficult case set
A useful evaluation set is not a museum of perfect demos. Start with the common path, then add cases that force the system to reveal its boundaries:
- an empty retrieval result;
- two sources that disagree;
- a request missing the field needed for authorization;
- a malformed tool response;
- a repeated event after a timeout;
- a long input that exceeds the normal context shape;
- a high-consequence action that should wait for approval;
- an evaluator disagreement with a clear human disposition.
Give each case a purpose, expected outcome, unacceptable outcome, and owner. Keep the fixture redacted and versioned. When a production incident becomes a case, record the mechanism, not just the transcript.
Make evaluators disagree usefully
Disagreement is not automatically noise. It can indicate an ambiguous rubric, a missing reference answer, a judge that lacks context, or a genuine product regression. Store the candidate output, baseline output, evidence, evaluator version, and reviewer reason together. The next action should follow the mechanism: improve the rubric, improve retrieval, repair the tool contract, or route the case to review.
Use three gates, not one score
A release gate should make bad trade-offs visible. Separate the checks into three layers:

The candidate advances only when each layer passes on its own; a strong average cannot open a failed gate.
- Hard controls: schema validity, authorization, policy blocks, required citations, and safe argument validation.
- Quality evidence: task success, groundedness, tool correctness, refusal quality, and human review on difficult cases.
- Operating limits: latency, cost, retry volume, queue delay, and unknown provider outcomes.
A candidate must pass the hard controls even when its quality score improves. It must show useful quality evidence without crossing operating limits. If a candidate fails one layer, record the reason and owner instead of averaging the failure away.
| Candidate result | Correct response |
|---|---|
| Quality up, safety stable, cost stable | Proceed to a controlled canary |
| Quality up, tool failures up | Hold and inspect the first divergent trace |
| Cost down, task completion down | Reject the optimization |
| Scores stable, complaints up | Revisit the rubric and sample selection |
| Evaluator passes rise without outcome movement | Audit evaluator drift |
A worked release decision
Suppose the baseline handles 1,000 support tasks. A candidate is tested on the same cases:
| Signal | Baseline | Candidate | Read |
|---|---|---|---|
| Correct task outcome | 884 | 901 | Improvement |
| Unsupported claim | 31 | 28 | Improvement |
| Tool argument failure | 7 | 19 | Regression |
| Median latency | 2.4s | 2.1s | Improvement |
| p95 latency | 8.9s | 10.7s | Regression |
| Cost per completed task | $0.018 | $0.021 | Trade-off |
The candidate is not ready for broad promotion. The task outcome improved, but the tool and tail-latency regressions can create expensive or unsafe customer experiences. A sensible next step is a canary limited to read-only cases while the team investigates whether the model is proposing more complex actions or whether argument validation changed.
Keep the decision record compact:
- Candidate: model, prompt, evaluator, and dataset versions.
- Observed win: +17 correct task outcomes on the fixed panel.
- Observed risk: tool argument failures and p95 latency increased.
- Scope: read-only canary, 10% of eligible traffic.
- Stop condition: any unsafe proposal or tool-failure rate above baseline plus agreed tolerance.
- Owner: the workflow team.
- Next review: after the first 200 canary tasks.
Instrument the evaluator itself
The evaluator is a production dependency. Track missing scores, parser failures, score distributions, judge-model version, rubric version, reference-data version, and evaluation cost. Alert when the evaluator suddenly marks nearly everything as a pass or when its output schema changes.
Here is a small illustrative gate. It is intentionally simple: the application still needs its own policy, cohort, and trace storage.
type Gate = "promote" | "hold" | "review";

function decide(input: {
  hardControlsPass: boolean;
  qualityImproved: boolean;
  operatingLimitsPass: boolean;
}): Gate {
  if (!input.hardControlsPass) return "hold";
  if (!input.operatingLimitsPass) return "review";
  return input.qualityImproved ? "promote" : "hold";
}
The code does not replace judgment. It makes the ordering explicit: safety and operating limits are checked before a quality improvement can earn promotion.
Leave the reader with the next move
Use the scorecard at the next candidate review:
- Write the task outcome and denominator.
- Select the smallest case set that covers common and costly failures.
- Version the candidate, evaluator, rubric, and evidence.
- Inspect the first divergence in representative traces.
- Apply hard-control, quality, and operating-limit gates separately.
- Choose a bounded rollout, named owner, and stop condition.
The best evaluation system is not the one with the most metrics. It is the one that helps a team make a clearer decision, find the first failure mechanism, and improve the workflow without hiding trade-offs.
Frequently asked questions
What is the best AI evaluation metric?
The best primary metric is the one that represents the user task. Add quality, reliability, cost, latency, and safety dimensions when they can change the release decision.
Can an LLM judge evaluate another LLM?
It can provide useful evidence, but validate its agreement with human or task-specific checks, monitor evaluator drift, and keep the evaluator version attached to every result.
How many examples are needed?
Enough to represent important cohorts and failure modes, with uncertainty reported honestly. A smaller, curated set is more useful than a larger set that excludes difficult cases.
How often should production evaluations run?
Run deterministic and critical safety checks on every relevant release. Sample production outcomes continuously or on a regular operating cadence, and re-run stable calibration cases whenever the model, prompt, evaluator, tool set, or reference data changes.
How should quality be balanced against cost and latency?
Keep quality, cost, and latency as separate dimensions with explicit limits. Promote only when the user outcome improves without crossing the agreed operating boundary; do not average a serious regression into a single composite score.
Practical field notes from the team building Tracify and operating AI agents in production.
Related posts
Next in the loop
AI Workflow Automation: A Safe Production Pattern
Keep reading →